Proteomics vs Genomics: How Much Does mRNA Tell You About Protein? Measured in 29 Human Tissues
The practical difference between genomics and proteomics, measured: in paired mRNA and protein data from 29 healthy human tissues, mRNA explained about 29% of the variation in protein levels, and a gene's mRNA and protein tracked each other across tissues only weakly (median Spearman 0.35).
Rewritten in October 2026. The earlier version of this page was a generic comparison table. This version answers the question behind it with data: I re-analysed a public dataset where mRNA and protein were measured in the same tissue samples, and every number below comes from that run.
The textbook answer to "proteomics vs genomics" is a list: the genome is mostly static, the proteome changes; DNA is easy to sequence, proteins are hard to measure. All true, and not much help when you're deciding whether you need proteomics at all. The practical question is narrower: if you already have RNA-seq, how much does it tell you about the proteins?
The Short Version
In paired transcriptome and proteome data from 29 healthy human tissues (Wang et al. 2019, Molecular Systems Biology):
| Question | Answer (my calculation from Wang et al. 2019, Table EV6) |
|---|---|
| Within one tissue, do genes with more mRNA have more protein? | Yes, moderately: Spearman 0.41–0.58 across tissues (median 0.52) |
| How much of the variation in protein level does mRNA explain? | About 29% (median R² of log values across genes; 19–37% by tissue; not corrected for measurement noise) |
| How far can two genes with the same mRNA level differ in protein? | The protein-per-mRNA ratio varies about 15–16-fold across the middle half of genes and about 740-fold across the middle 90% |
| If a gene's mRNA goes up from one tissue to another, does its protein? | Only weakly: median Spearman across tissues 0.35. 12% of genes had a negative correlation, but almost none significantly (38 genes at p < 0.05, 8 after FDR correction); 42% were significantly positive |
| Range of abundance, same genes, one tissue (liver) | For the 7,481 genes with both values, protein spans ~4.8 orders of magnitude (1st–99th percentile) and mRNA ~2.7. Over all detected molecules the paper reports ~8 orders for protein and ~4 for mRNA |
So mRNA is a useful, but rough, guide to protein abundance. For a specific gene in a specific comparison, you can't rely on it even for the direction of change: for most genes the co-variation across tissues is weak or not detectable.
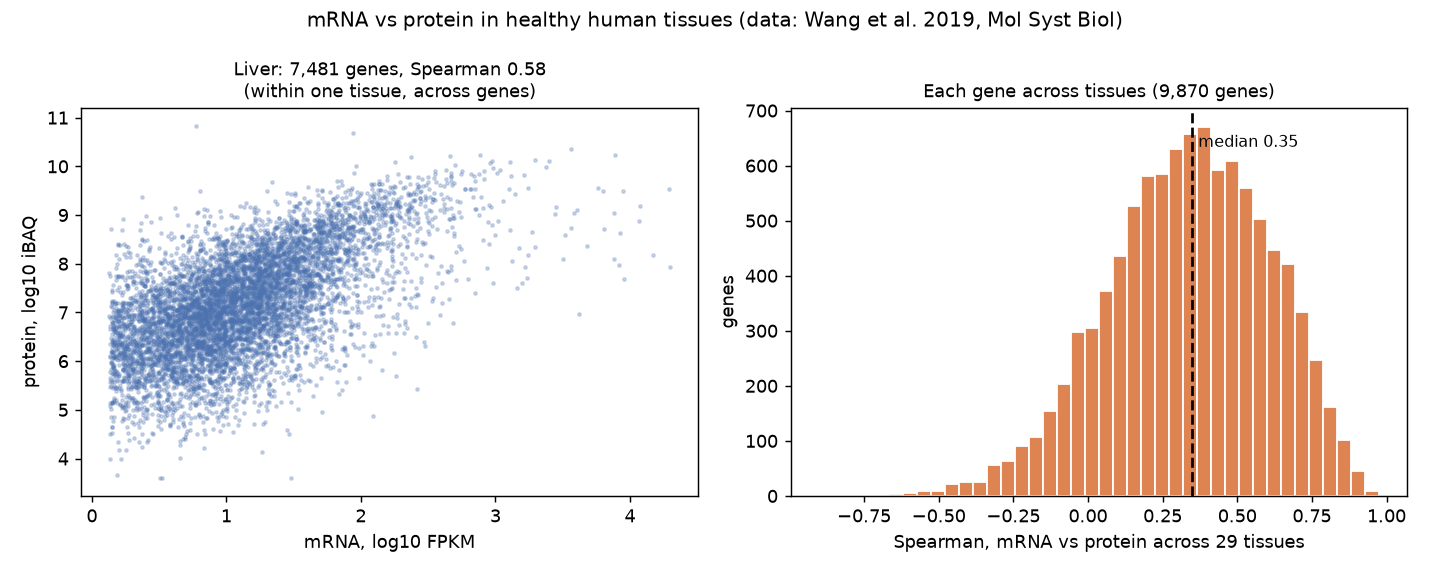 Left: every gene in liver, mRNA against protein. Right: for each gene, how well its mRNA and protein track each other across 29 tissues.
The Data
Wang D. et al. (2019) measured paired samples of 29 healthy human tissues with both RNA-seq and deep label-free proteomics. Their Table EV6 lists, for 9,870 genes detected as both transcript and protein in at least 10 tissues, the log10 mRNA level (FPKM) and log10 protein level (iBAQ) per tissue. That is what I used; no reprocessing of raw files.
Two different questions are hiding in "mRNA–protein correlation", and they give different answers:
- Across genes, within a tissue: abundant transcripts tend to belong to abundant proteins. This is the 0.52.
- Across tissues, within a gene: when this gene's mRNA is higher in tissue A than B, is its protein higher too? This is the 0.35, and it is the one that matters when you compare conditions.
The Code
Python 3.12, pandas and SciPy. This reproduces the two headline numbers from the supplementary file:
import numpy as np, pandas as pd
from scipy.stats import spearmanr

# Wang et al. 2019, Table EV6, sheet A: log10 FPKM (29 tissues), then log10 iBAQ (same 29 tissues)
t = pd.read_excel("Table_EV6.xlsx", sheet_name="A. Protein vs mRNA correlation", header=None)
mrna = t.iloc[2:, 2:31].astype(float).to_numpy()
prot = t.iloc[2:, 31:60].astype(float).to_numpy()

def rho(x, y):
    ok = ~np.isnan(x) & ~np.isnan(y)
    return spearmanr(x[ok], y[ok])[0] if ok.sum() >= 10 else np.nan

within_tissue = [rho(mrna[:, j], prot[:, j]) for j in range(29)]      # across genes, per tissue
within_gene = [rho(mrna[i], prot[i]) for i in range(len(mrna))]       # across tissues, per gene

print(f"{len(mrna)} genes x 29 tissues")
print(f"across genes, per tissue:  median rho {np.median(within_tissue):.2f} "
      f"(range {min(within_tissue):.2f}-{max(within_tissue):.2f})")
print(f"across tissues, per gene:  median rho {np.nanmedian(within_gene):.2f}, "
      f"{np.nanmean(np.array(within_gene) < 0):.0%} of genes negative")
Output:
9870 genes x 29 tissues
across genes, per tissue:  median rho 0.52 (range 0.41-0.58)
across tissues, per gene:  median rho 0.35, 12% of genes negative
My per-gene correlations matched the paper's own per-gene column exactly (Pearson 1.000 between the two), so the file is being read correctly. The R², ratio spreads and dynamic ranges in the table above came from the longer script in the same analysis.
What This Means in Practice
Where RNA-seq is enough. If you need a broad picture (which pathways are active, which cell types are present, large expression programmes), mRNA does a reasonable job, is cheaper, and covers far more genes. In the same study (Wang et al. 2019), RNA-seq detected on average 12,262 protein-coding genes per tissue (at least 1 FPKM) and deep, fractionated proteomics 10,541 genes per tissue; 18,072 vs 13,640 over all tissues. Deep proteomics gets close; a typical single-shot run sees far fewer proteins.
Where you need proteomics. When the protein itself is the object: abundance of a specific protein, secreted or plasma proteins (the mRNA sits in the tissue that made the protein, for example the liver for albumin, not in the sample you measured), post-translational modifications, protein turnover, and any claim about a single gene going up or down. With a median within-gene agreement of 0.35, an mRNA change is a hypothesis about the protein, not a measurement of it.
Why they differ. Translation rates and protein half-lives differ widely between proteins, which accounts for part of the ~740-fold spread in the protein-per-mRNA ratio. Measurement error, cell-type mix and contamination (for example blood in heart tissue) account for the rest: iBAQ and FPKM are both approximate absolute measures, and proteomics misses low-abundance proteins.
For multi-omics designs: measure both on the same samples if the question is about regulation. Inferring one from the other across a whole study hides exactly the genes where they disagree, which are often the interesting ones.
The Differences That Still Hold (Briefly)
| Genomics / transcriptomics | Proteomics | |
|---|---|---|
| Molecule | DNA, RNA | Proteins and peptides |
| Amplification | Yes (PCR) | No: you measure what is there |
| Typical coverage | Most expressed genes | A few thousand to ~10,000 proteins per run, biased to abundant ones |
| Main platform | Sequencing | LC-MS/MS (DDA or DIA) |
| What it can't see | Protein amounts, modifications, secreted proteins | Low-abundance proteins, many splice isoforms |
For the practical side of the mass spectrometry workflow, see how to analyse mass spectrometry data.
Limits
- One dataset: healthy adult tissues, bulk samples, label-free iBAQ and FPKM. Cell lines, disease, time courses and other quantification methods give different numbers; published estimates of mRNA–protein agreement range widely for this reason.
- Only genes detected as both mRNA and protein in at least 10 tissues are included (9,870). Genes with transcripts but no detected protein, and the reverse, are outside this analysis, which makes the agreement look better than for the whole genome.
- Correlation across 29 tissues per gene is noisy for genes with little variation between tissues; a low correlation can mean "little to correlate" rather than disagreement. Split by how much a gene's mRNA varies across tissues, the median correlation rises from 0.23 in the least variable quarter of genes to 0.54 in the most variable.
- Each tissue came from a different donor, so "across tissues" also means "across people". It is an analogy for comparing conditions in your own experiment, not the same thing.
Code and outputs: the scripts and result tables for this post are on GitHub in sbmlab-benchmarks/mrna-protein-wang2019.
Related
- DIA-NN on a known-answer benchmark
- DESeq2 vs edgeR vs limma for RNA-seq
- Bioinformatics databases, tested
References
- Wang D. et al. (2019). A deep proteome and transcriptome abundance atlas of 29 healthy human tissues. Molecular Systems Biology 15:e8503. doi:10.15252/msb.20188503
Related
A MaxQuant Run Took Me 10+ Hours on a Windows PC — the Checks I Now Do Before Pressing Start
Oct 1 · 7 min read
BioinformaticsSame Gene List, Different GO Enrichment: How Much the GO Release Changes the Result (2016 to 2025, Measured)
Nov 6 · 10 min read
BioinformaticsCorrect Batch Effects, Then Test? With an Unbalanced Design, ComBat Turns a 5% False-Positive Target into 29%
Nov 4 · 10 min read
BioinformaticsCan an LLM Run an RNA-seq Analysis on Its Own? Building ARIA, a Decision-Aware Transcriptome Framework
Jun 2 · 6 min read